记录19c ASM磁盘掉线触发ORA-59048故障处理

联系:手机/微信(+86 17813235971) QQ(107644445)QQ咨询惜分飞

标题:记录19c ASM磁盘掉线触发ORA-59048故障处理

作者:惜分飞©版权所有[未经本人同意,不得以任何形式转载,否则有进一步追究法律责任的权利.]

在一套Oracle 19c RAC环境中有ocr/vote所在磁盘组有磁盘offline

ASMCMD> lsdg  
State    Type    Rebal  Sector  Logical_Sector  Block       AU  Total_MB   Free_MB  Req_mir_free_MB  Usable_file_MB  Offline_disks  Voting_files  Name
MOUNTED  EXTERN  N         512             512   4096  4194304  24576000  19047940                0        19047940              0             N  DATA/
MOUNTED  EXTERN  N         512             512   4096  4194304   2500608   1043156                0         1043156              0             N  FRA/
MOUNTED  NORMAL  Y         512             512   4096  4194304    102400    101576            51200           25188              1             Y  SYSDG/
ASMCMD> lsdsk -G sysdg
Path

/dev/asm_ocr1
/dev/asm_ocr2

ASMCMD>

在sqlplus中查询具体信息

[grid@dbserver1 ~]$ sqlplus / as sysdba

SQL*Plus: Release 19.0.0.0.0 - Production on Fri Nov 6 19:31:39 2026
Version 19.16.0.0.0

Copyright (c) 1982, 2022, Oracle.  All rights reserved.


Connected to:
Oracle Database 19c Enterprise Edition Release 19.0.0.0.0 - Production
Version 19.16.0.0.0

SQL> col path for a40
SQL> set lines 150
SQL> select disk_number,MOUNT_STATUS,HEADER_STATUS,MODE_STATUS,STATE,CREATE_DATE,MOUNT_DATE,
   2 name,path from v$asm_disk where group_number=3;

DISK_NUMBER MOUNT_S HEADER_STATU MODE_ST STATE    CREATE_DA MOUNT_DAT NAME                  PATH
----------- ------- ------------ ------- -------- --------- --------- --------------------- -------------
          2 MISSING UNKNOWN      OFFLINE FORCING  07-SEP-22 22-OCT-26 _DROPPED_0002_SYSDG
          1 CACHED  MEMBER       ONLINE  NORMAL   07-SEP-22 22-OCT-26 SYSDG_0001           /dev/asm_ocr2
          0 CACHED  MEMBER       ONLINE  NORMAL   07-SEP-22 22-OCT-26 SYSDG_0000           /dev/asm_ocr1

这里显示被丢失的磁盘状态处于missing,而且state=FORCING,磁盘名字变为_DROPPED_0002_SYSDG,这里表现出来的是磁盘应该是不可访问,然后asm 自动踢掉该盘,但是没有正常清除元数据.查询磁盘reblance状态

SQL> SELECT GROUP_NUMBER, OPERATION, STATE, POWER, ERROR_CODE
  2      FROM GV$ASM_OPERATION
  3      WHERE GROUP_NUMBER = 3;

GROUP_NUMBER OPERA STAT      POWER ERROR_CODE
------------ ----- ---- ---------- --------------------------------------------
           3 REBAL WAIT          1
           3 REBAL ERRS          1 ORA-59048
           3 REBAL WAIT          1
           3 REBAL WAIT          1
           3 REBAL WAIT          1
           3 REBAL ERRS          1 ORA-59048
           3 REBAL WAIT          1
           3 REBAL WAIT          1

该磁盘组在reblance的过程中由于遭遇了ORA-59048导致无法清除掉异常磁盘元数据.关于ORA-59048的官方解释

SQL> !oerr ora 59048
59048, 0000, "Redundancy could not be restored in group '%0!s'."
// *Cause:  An attempt to restore redundancy during rebalance failed for some
//          user data or ASM metadata due to the presence of dropping or
//          forcing disks.
// *Action: Add back all the disks in DROPPING or FORCING state. If this is an
//          Oracle appliance, also add back all the missing disks.

出现该问题的原因是由于
In 12.1.0.2 ASM and higher releases, it is not allowed to Normal Drop the Failgroup in a Normal/High Redundancy Diskgroup if it lowers the Failgroup count below 3 for Normal Redundancy Diskgroup and below 5 for High Redundancy Diskgroup.Any attempt to force drop Failgroup will not expel the disks completely and leave the disks in “FORCING” state.
解决该问题官方的建议:
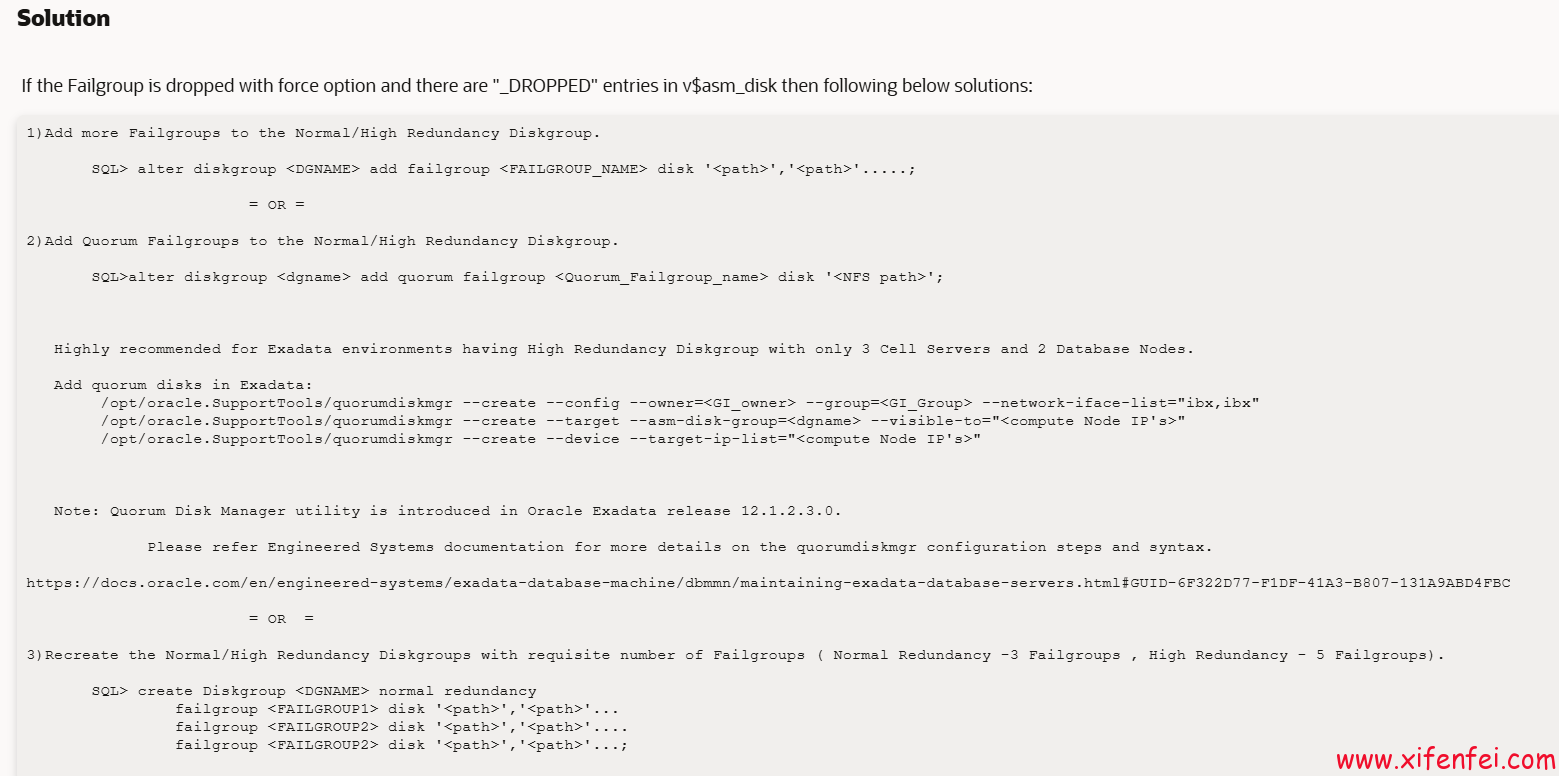
ora-59048


查看asm的alert日志确认该磁盘组当时具体状态,最早确实是由于/dev/asm_ocr3这个盘访问报io错误

2026-10-25T10:20:06.228405+08:00
NOTE: SMON did instance recovery for group FRA domain 2
NOTE: SMON detected lock domain 3 invalid at system inc 4 10/25/26 10:20:05
WARNING: Read Failed. group:3 disk:2 AU:0 offset:0 size:4096
path:/dev/asm_ocr3
	 incarnation:0xf0f3546f asynchronous result:'I/O error' ioreason:2818 why:11
	 subsys:System krq:0x7ffff294e3d8 bufp:0x7ffff2910000 osderr1:0x69b5 osderr2:0x0
	 IO elapsed time: 0 usec Time waited on I/O: 0 usec
NOTE: SMON starting instance recovery of group SYSDG domain 3 inc 4 (mounted) at 10/25/26 10:20:05
NOTE: 10/25/26 10:20:05 SYSDG.F1X0 found on disk 0 au 10 fcn 0.0 datfmt 1
NOTE: 10/25/26 10:20:05 SYSDG.F1X0 found on disk 1 au 10 fcn 0.0 datfmt 1
NOTE: SMON will attempt offline of disk 2 - no header
NOTE: cache initiating offline of disk 2 group SYSDG
NOTE: checking PST: grp = 3
2026-10-25T10:20:06.235215+08:00
GMON checking disk modes for group 3 at 20 for pid 23, osid 67867
2026-10-25T10:20:06.236213+08:00
NOTE: checking PST for grp 3 done.
NOTE: initiating PST update: grp 3 (SYSDG), dsk = 2/0xf0f3546f, mask = 0x6a, op = clear mandatory
2026-10-25T10:20:06.236627+08:00
GMON updating disk modes for group 3 at 21 for pid 23, osid 67867
cluster guid (11de9e990b017f7ebf235441d97d8d20) generated for PST Hbeat for instance 1
WARNING: Write Failed. group:3 disk:2 AU:1 offset:4190208 size:4096
path:/dev/asm_ocr3
	 incarnation:0xf0f3546f synchronous result:'I/O error' ioreason:13825 why:54
	 subsys:System krq:0x7ffff2606068 bufp:0x7ffff7e28000 osderr1:0x69c0 osderr2:0x0
	 IO elapsed time: 0 usec Time waited on I/O: 0 usec
WARNING: found another non-responsive disk 2.4042478703 (SYSDG_0002) that will be offlined 

然后asm 自动踢掉该磁盘,并尝试进行reblance

2026-10-25T10:20:22.547474+08:00
NOTE: cache closing disk 2 of grp 3: SYSDG_0002
2026-10-25T10:20:22.555942+08:00
NOTE: cache closing disk 2 of grp 3: (not open) SYSDG_0002
2026-10-25T10:20:22.558591+08:00
NOTE: PST update grp = 3 completed successfully 
2026-10-25T10:20:24.398958+08:00
Errors in file /u01/app/grid/diag/asm/+asm/+ASM1/trace/+ASM1_ora_24660.trc:
ORA-15078: ASM diskgroup was forcibly dismounted
2026-10-25T10:20:24.489753+08:00
NOTE: Attempting voting file refresh on diskgroup SYSDG
NOTE: Refresh completed on diskgroup SYSDG. Found 2 voting file(s).
NOTE: Voting file relocation is required in diskgroup SYSDG
NOTE: Attempting voting file relocation on diskgroup SYSDG
NOTE: Successful voting file relocation on diskgroup SYSDG
2026-10-25T10:20:24.970204+08:00
WARNING: Disk 2 (SYSDG_0002) in group 3 will be dropped in: (0) secs on ASM inst 1
NOTE: The rdbms compatibility of group SYSDG is 10.1.0.0.0
WARNING: PST-initiated drop of 1 disk(s) in group 3(.2297668793))
2026-10-25T10:20:24.977298+08:00
SQL> alter diskgroup SYSDG drop disk SYSDG_0002 force /* ASM SERVER */ 
2026-10-25T10:20:24.989168+08:00
NOTE: cache closing disk 2 of grp 3: (not open) SYSDG_0002
NOTE: GroupBlock outside rolling migration privileged region
2026-10-25T10:20:25.020909+08:00
NOTE: client +ASM1:+ASM:dbsvr-cluster no longer has group 1 (DATA) mounted
2026-10-25T10:20:25.028211+08:00
NOTE: requesting all-instance membership refresh for group=3
2026-10-25T10:20:25.033193+08:00
GMON updating for reconfiguration, group 3 at 32 for pid 47, osid 37477
2026-10-25T10:20:25.033508+08:00
NOTE: cache closing disk 2 of grp 3: (not open) SYSDG_0002
2026-10-25T10:20:25.036948+08:00
NOTE: group 3 PST updated.
2026-10-25T10:20:25.037055+08:00
NOTE: cache closing disk 2 of grp 3: (not open) SYSDG_0002
2026-10-25T10:20:25.138731+08:00
NOTE: membership refresh pending for group 3/0x88f3a4b9 (SYSDG)
NOTE: Attempting voting file refresh on diskgroup SYSDG
NOTE: Refresh completed on diskgroup SYSDG. Found 2 voting file(s).
NOTE: Voting file relocation is required in diskgroup SYSDG
NOTE: Attempting voting file relocation on diskgroup SYSDG
NOTE: Successful voting file relocation on diskgroup SYSDG
2026-10-25T10:20:25.243884+08:00
NOTE: cache closing disk 2 of grp 3: (not open) _DROPPED_0002_SYSDG
2026-10-25T10:20:25.244375+08:00
GMON querying group 3 at 33 for pid 26, osid 67882
2026-10-25T10:20:25.244593+08:00
NOTE: cache closing disk 2 of grp 3: (not open) _DROPPED_0002_SYSDG
2026-10-25T10:20:25.264523+08:00
SUCCESS: refreshed membership for 3/0x88f3a4b9 (SYSDG)
2026-10-25T10:20:25.265056+08:00
SUCCESS: alter diskgroup SYSDG drop disk SYSDG_0002 force /* ASM SERVER */
2026-10-25T10:20:25.267949+08:00
NOTE: starting rebalance of group 3/0x88f3a4b9 (SYSDG) at power 1
NOTE: starting process ARBA
Starting background process ARBA
2026-10-25T10:20:25.320353+08:00
ARBA started with pid=34, OS id=38626 
NOTE: starting process ARB0
Starting background process ARB0
2026-10-25T10:20:25.348943+08:00
ARB0 started with pid=39, OS id=38628 
NOTE: assigning ARBA to group 3/0x88f3a4b9 (SYSDG) to compute estimates
NOTE: assigning ARB0 to group 3/0x88f3a4b9 (SYSDG) with 1 parallel I/O
NOTE: starting priority rebalance
2026-10-25T10:20:25.741091+08:00
NOTE: 10/25/26 10:20:24 SYSDG.F1X0 copy 3 relocating from 2:10 to 65534:4294967294 at FCN 0.437476
NOTE: header on disk 0 advanced to format #2 using fcn 0.0
NOTE: F1B1 fcn on disk 0 synced at fcn 0.437476
NOTE: header on disk 1 advanced to format #2 using fcn 0.0
NOTE: F1B1 fcn on disk 1 synced at fcn 0.437476
2026-10-25T10:20:27.284097+08:00
NOTE: starting priority rebalance
NOTE: stopping process ARB0
NOTE: stopping process ARBA
NOTE: Attempting voting file refresh on diskgroup SYSDG
NOTE: Refresh completed on diskgroup SYSDG. Found 2 voting file(s).
NOTE: Starting expel slave for group 3/0x88f3a4b9 (SYSDG)
2026-10-25T10:20:27.638396+08:00
NOTE: GroupBlock outside rolling migration privileged region
NOTE: requesting all-instance membership refresh for group=3
2026-10-25T10:20:27.682346+08:00
GMON updating for reconfiguration, group 3 at 34 for pid 34, osid 38635
2026-10-25T10:20:27.682672+08:00
NOTE: cache closing disk 2 of grp 3: (not open) _DROPPED_0002_SYSDG
2026-10-25T10:20:27.686280+08:00
NOTE: group 3 PST updated.
2026-10-25T10:20:27.686317+08:00
NOTE: cache closing disk 2 of grp 3: (not open) _DROPPED_0002_SYSDG
SUCCESS: grp 3 disk _DROPPED_0002_SYSDG emptied
NOTE: grp 3 disk 2 not expelled because ASM metadata redundancy has 
      not been restored due to an insufficientnumber of failure groups

比较简单的而且安全的做法是客户划分一块新的ocr盘上来,然后udev配置并加入到该磁盘组中即可.但是由于该客户存储没有新空间,只能分析尝试把原盘该加入进来.先确认该盘现在读写是否正常(存储故障已经修复)
1. kfed read 或者dd读取该盘确认正常
2. 由于该盘依旧属于sysdg磁盘组的member,无法直接加入

SQL> alter diskgroup sysdg add disk '/dev/asm_ocr3' ;
alter diskgroup sysdg add disk '/dev/asm_ocr3'
*
ERROR at line 1:
ORA-15032: not all alterations performed
ORA-15033: disk 'DATA01' is already part of diskgroup


SQL> ALTER DISKGROUP SYSDG ADD DISK '/dev/asm_ocr3' 
2026-11-06T19:35:15.741021+08:00
NOTE: GroupBlock outside rolling migration privileged region
2026-11-06T19:35:15.909199+08:00
NOTE: cache closing disk 2 of grp 3: (not open) _DROPPED_0002_SYSDG
NOTE: Assigning number (3,3) to disk (/dev/asm_ocr3)
NOTE: requesting all-instance membership refresh for group=3
2026-11-06T19:35:15.998569+08:00
NOTE: membership refresh pending for group 3/0x88f3a4b9 (SYSDG)
2026-11-06T19:35:16.018117+08:00
NOTE: cache closing disk 2 of grp 3: (not open) _DROPPED_0002_SYSDG
2026-11-06T19:35:16.034067+08:00
GMON querying group 3 at 43 for pid 26, osid 67882
2026-11-06T19:35:16.035115+08:00
NOTE: cache closing disk 2 of grp 3: (not open) _DROPPED_0002_SYSDG
GMON querying group 3 at 44 for pid 26, osid 67882
2026-11-06T19:35:16.035967+08:00
NOTE: cache closing disk 2 of grp 3: (not open) _DROPPED_0002_SYSDG
2026-11-06T19:35:16.097552+08:00
NOTE: cache closing disk 2 of grp 3: (not open) _DROPPED_0002_SYSDG
GMON querying group 3 at 45 for pid 26, osid 67882
2026-11-06T19:35:16.098168+08:00
NOTE: cache closing disk 2 of grp 3: (not open) _DROPPED_0002_SYSDG
2026-11-06T19:35:16.119434+08:00
SUCCESS: refreshed membership for 3/0x88f3a4b9 (SYSDG)
2026-11-06T19:35:16.263264+08:00
ORA-15032: not all alterations performed
ORA-15033: disk '/dev/asm_ocr3' belongs to diskgroup "SYSDG"

2026-11-06T19:35:16.263630+08:00
ERROR: ALTER DISKGROUP SYSDG ADD DISK '/dev/asm_ocr3'

3. 直接使用force强制加入,也可以先dd掉磁盘头然后加入

SQL> ALTER DISKGROUP SYSDG ADD FAILGROUP SYSDG_0002 DISK '/dev/asm_ocr3' FORCE REBALANCE POWER 1;

Diskgroup altered.

SQL> SELECT GROUP_NUMBER, OPERATION, STATE, POWER, ERROR_CODE
  2      FROM GV$ASM_OPERATION
  3      WHERE GROUP_NUMBER = 3;

GROUP_NUMBER OPERA STAT      POWER ERROR_CODE
------------ ----- ---- ---------- --------------------------------------------
           3 REBAL REAP          1
           3 REBAL DONE          1
           3 REBAL DONE          1
           3 REBAL DONE          1
           3 REBAL WAIT          1
           3 REBAL WAIT          1
           3 REBAL WAIT          1
           3 REBAL WAIT          1

8 rows selected.

SQL> col path for a40
SQL> set lines 150
SQL> select disk_number,MOUNT_STATUS,HEADER_STATUS,MODE_STATUS,STATE,CREATE_DATE,MOUNT_DATE,
   2 name,path from v$asm_disk where group_number=3;

DISK_NUMBER MOUNT_S HEADER_STATU MODE_ST STATE    CREATE_DA MOUNT_DAT NAME         PATH
----------- ------- ------------ ------- -------- --------- --------- ------------ --------------
          1 CACHED  MEMBER       ONLINE  NORMAL   07-SEP-22 22-OCT-26 SYSDG_0001   /dev/asm_ocr2
          3 CACHED  MEMBER       ONLINE  NORMAL   06-NOV-26 06-NOV-26 SYSDG_0003   /dev/asm_ocr3
          0 CACHED  MEMBER       ONLINE  NORMAL   07-SEP-22 22-OCT-26 SYSDG_0000   /dev/asm_ocr1

磁盘成功加入,并且reblance完成,而且_DROPPED_0002_SYSDG磁盘记录也完全清除

[grid@dbserver1 ~]$ asmcmd
ASMCMD> lsdg
State    Type    Rebal  Sector  Logical_Sector  Block       AU  Total_MB   Free_MB  Req_mir_free_MB  Usable_file_MB  Offline_disks  Voting_files  Name
MOUNTED  EXTERN  N         512             512   4096  4194304  24576000  19047940                0        19047940              0             N  DATA/
MOUNTED  EXTERN  N         512             512   4096  4194304   2500608   1043156                0         1043156              0             N  FRA/
MOUNTED  NORMAL  N         512             512   4096  4194304    153600    152524            51200           50662              0             Y  SYSDG/
ASMCMD> lsdsk -G sysdg
Path
/dev/asm_ocr1
/dev/asm_ocr2
/dev/asm_ocr3
ASMCMD> 

整个加入磁盘asm alert日志记录

2026-11-06T19:35:31.368323+08:00
SQL> ALTER DISKGROUP SYSDG ADD FAILGROUP SYSDG_0002 DISK '/dev/asm_ocr3' FORCE REBALANCE POWER 1
2026-11-06T19:35:31.369612+08:00
NOTE: GroupBlock outside rolling migration privileged region
2026-11-06T19:35:31.480932+08:00
NOTE: cache closing disk 2 of grp 3: (not open) _DROPPED_0002_SYSDG
NOTE: Assigning number (3,3) to disk (/dev/asm_ocr3)
NOTE: requesting all-instance membership refresh for group=3
NOTE: Disk 3 in group 3 is assigned fgnum=3
NOTE: discarding redo for group 3 disk 3
NOTE: initializing header (replicated) on grp 3 disk SYSDG_0003
NOTE: initializing header on grp 3 disk SYSDG_0003
NOTE: requesting all-instance disk validation for group=3
2026-11-06T19:35:31.544284+08:00
NOTE: skipping rediscovery for group 3/0x88f3a4b9 (SYSDG) on local instance.
2026-11-06T19:35:31.685931+08:00
NOTE: running client discovery for group 3 (reqid:9868412322975013714)
NOTE: requesting all-instance disk validation for group=3
2026-11-06T19:35:31.690689+08:00
NOTE: skipping rediscovery for group 3/0x88f3a4b9 (SYSDG) on local instance.
2026-11-06T19:35:31.798128+08:00
NOTE: running client discovery for group 3 (reqid:9868412322975027894)
NOTE: Allocated 1 DD reserve extents for group 3 (SYSDG)
NOTE: Allocated 2 VAT reserve extents for group 3 (SYSDG).
NOTE: Adding disk 3 (SYSDG_0003) to grp 3 (SYSDG) (12800 AUs)
2026-11-06T19:35:32.800462+08:00
GMON updating for reconfiguration, group 3 at 47 for pid 34, osid 32035
2026-11-06T19:35:32.800767+08:00
NOTE: cache closing disk 2 of grp 3: (not open) _DROPPED_0002_SYSDG
NOTE: group SYSDG: updated PST location: disks 0000 0001 0003
2026-11-06T19:35:32.806670+08:00
NOTE: cache closing disk 2 of grp 3: (not open) _DROPPED_0002_SYSDG
2026-11-06T19:35:32.806867+08:00
NOTE: group 3 PST updated.
2026-11-06T19:35:32.817316+08:00
NOTE: membership refresh pending for group 3/0x88f3a4b9 (SYSDG)
NOTE: Attempting voting file refresh on diskgroup SYSDG
NOTE: Refresh completed on diskgroup SYSDG. Found 2 voting file(s).
NOTE: Voting file relocation is required in diskgroup SYSDG
2026-11-06T19:35:32.870762+08:00
NOTE: cache closing disk 2 of grp 3: (not open) _DROPPED_0002_SYSDG
2026-11-06T19:35:32.871172+08:00
GMON querying group 3 at 48 for pid 26, osid 67882
2026-11-06T19:35:32.871938+08:00
NOTE: cache closing disk 2 of grp 3: (not open) _DROPPED_0002_SYSDG
NOTE: cache opening disk 3 of grp 3: SYSDG_0003 path:/dev/asm_ocr3
2026-11-06T19:35:33.135859+08:00
NOTE: Attempting voting file refresh on diskgroup SYSDG
NOTE: Refresh completed on diskgroup SYSDG. Found 2 voting file(s).
NOTE: Voting file relocation is required in diskgroup SYSDG
NOTE: Attempting voting file relocation on diskgroup SYSDG
NOTE: Failed voting file relocation on diskgroup SYSDG
2026-11-06T19:35:33.202862+08:00
NOTE: cache closing disk 2 of grp 3: (not open) _DROPPED_0002_SYSDG
2026-11-06T19:35:33.203321+08:00
GMON querying group 3 at 49 for pid 26, osid 67882
2026-11-06T19:35:33.203546+08:00
NOTE: cache closing disk 2 of grp 3: (not open) _DROPPED_0002_SYSDG
2026-11-06T19:35:33.248381+08:00
SUCCESS: refreshed membership for 3/0x88f3a4b9 (SYSDG)
2026-11-06T19:35:33.249044+08:00
SUCCESS: ALTER DISKGROUP SYSDG ADD FAILGROUP SYSDG_0002 DISK '/dev/asm_ocr3' FORCE REBALANCE POWER 1
2026-11-06T19:35:33.249626+08:00
NOTE: starting rebalance of group 3/0x88f3a4b9 (SYSDG) at power 1
NOTE: starting process ARBA
Starting background process ARBA
2026-11-06T19:35:33.300642+08:00
ARBA started with pid=39, OS id=32653
2026-11-06T19:35:33.300642+08:00
ARBA started with pid=39, OS id=32653
NOTE: starting process ARB0
Starting background process ARB0
2026-11-06T19:35:33.330349+08:00
ARB0 started with pid=40, OS id=32655
NOTE: assigning ARBA to group 3/0x88f3a4b9 (SYSDG) to compute estimates
NOTE: assigning ARB0 to group 3/0x88f3a4b9 (SYSDG) with 1 parallel I/O
NOTE: starting priority rebalance
2026-11-06T19:35:33.862973+08:00
NOTE: group 3, file 1, extent 0: successful reread of 256 block(s)
NOTE: header on disk 3 advanced to format #2 using fcn 0.0
NOTE: F1X0 on disk 3 (fmt 2) relocated at fcn 0.442279: AU 0 -> AU 10
NOTE: 11/06/26 19:35:33 SYSDG.F1X0 copy 3 relocating from 65534:4294967294 to 3:10 at FCN 0.442279
NOTE: F1B1 fcn on disk 0 synced at fcn 0.442279
NOTE: F1B1 fcn on disk 1 synced at fcn 0.442279
…………
NOTE: group 3, file 121, extent 7: successful reread of 256 block(s)
NOTE: group 3, file 255, extent 2147483648: successful reread of 256 block(s)
2026-11-06T19:35:43.100750+08:00
NOTE: starting priority rebalance
NOTE: Starting expel slave for group 3/0x88f3a4b9 (SYSDG)
2026-11-06T19:35:43.270964+08:00
NOTE: GroupBlock outside rolling migration privileged region
NOTE: requesting all-instance membership refresh for group=3
2026-11-06T19:35:43.373350+08:00
GMON updating for reconfiguration, group 3 at 50 for pid 45, osid 32714
2026-11-06T19:35:43.373665+08:00
NOTE: cache closing disk 2 of grp 3: (not open) _DROPPED_0002_SYSDG
2026-11-06T19:35:43.375552+08:00
NOTE: group 3 PST updated.
SUCCESS: grp 3 disk _DROPPED_0002_SYSDG emptied
NOTE: Expelling disk 2 (_DROPPED_0002_SYSDG) from grp 3 (SYSDG)
2026-11-06T19:35:43.414788+08:00
GMON updating for reconfiguration, group 3 at 51 for pid 45, osid 32714
2026-11-06T19:35:43.415757+08:00
NOTE: cache closing disk 2 of grp 3: (not open) _DROPPED_0002_SYSDG
2026-11-06T19:35:43.420906+08:00
NOTE: group 3 PST updated.
NOTE: grp 3 disk 2 expelled from the PST.
2026-11-06T19:35:43.528766+08:00
NOTE: membership refresh pending for group 3/0x88f3a4b9 (SYSDG)
2026-11-06T19:35:43.537768+08:00
GMON querying group 3 at 52 for pid 26, osid 67882
GMON querying group 3 at 53 for pid 26, osid 67882
2026-11-06T19:35:43.559379+08:00
NOTE: Disk _DROPPED_0002_SYSDG in mode 0x0 marked for de-assignment
SUCCESS: refreshed membership for 3/0x88f3a4b9 (SYSDG)
2026-11-06T19:35:44.127190+08:00
NOTE: starting priority rebalance
NOTE: stopping process ARB0
NOTE: stopping process ARBA
2026-11-06T19:35:44.568463+08:00
NOTE: Attempting voting file refresh on diskgroup SYSDG
NOTE: Refresh completed on diskgroup SYSDG. Found 3 voting file(s).
NOTE: Starting expel slave for group 3/0x88f3a4b9 (SYSDG)
2026-11-06T19:35:44.593489+08:00
NOTE: GroupBlock outside rolling migration privileged region
NOTE: requesting all-instance membership refresh for group=3
2026-11-06T19:35:44.607062+08:00
NOTE: membership refresh pending for group 3/0x88f3a4b9 (SYSDG)
2026-11-06T19:35:44.610642+08:00
GMON querying group 3 at 54 for pid 26, osid 67882
2026-11-06T19:35:44.654503+08:00
SUCCESS: refreshed membership for 3/0x88f3a4b9 (SYSDG)
2026-11-06T19:35:46.278541+08:00
SUCCESS: rebalance completed for group 3/0x88f3a4b9 (SYSDG)
NOTE: Attempting voting file refresh on diskgroup SYSDG
NOTE: Refresh completed on diskgroup SYSDG. Found 3 voting file(s).

aix平台Oracle数据库由于断电无法启动故障处理

联系:手机/微信(+86 17813235971) QQ(107644445)QQ咨询惜分飞

标题:aix平台Oracle数据库由于断电无法启动故障处理

作者:惜分飞©版权所有[未经本人同意,不得以任何形式转载,否则有进一步追究法律责任的权利.]

一套运行在aix环境的的10.2.0.4 rac库,由于异常断电导致数据库无法正常启动,报错为ORA-00600 6101。alert日志报错如下

Tue Oct 13 18:32:04 2026
ALTER DATABASE OPEN
This instance was first to open
Tue Oct 13 18:32:04 2026
Beginning crash recovery of 1 threads
 parallel recovery started with 15 processes
Tue Oct 13 18:32:08 2026
Started redo scan
Tue Oct 13 18:32:08 2026
Completed redo scan
 2573 redo blocks read, 396 data blocks need recovery
Tue Oct 13 18:32:08 2026
Started redo application at
 Thread 2: logseq 61170, block 1720185
Tue Oct 13 18:32:08 2026
Recovery of Online Redo Log: Thread 2 Group 4 Seq 61170 Reading mem 0
  Mem# 0: /oracle/oradata/db_ro41_1g
  Mem# 1: /oracle/oradata/db_ro42_1g
Tue Oct 13 18:32:08 2026
RECOVERY OF THREAD 2 STUCK AT BLOCK 63042 OF FILE 3
Tue Oct 13 18:32:08 2026
RECOVERY OF THREAD 2 STUCK AT BLOCK 38304 OF FILE 3
Tue Oct 13 18:32:08 2026
Errors in file /oracle/admin/orcl/bdump/orcl1_p001_123772.trc:
ORA-00600: internal error code, arguments: [6101], [16], [728], [32], [], [], [], []
Tue Oct 13 18:32:08 2026
Hex dump of (file 3, block 61217) in trace file /oracle/admin/orcl/bdump/orcl1_p013_254256.trc
Corrupt block relative dba: 0x00c0ef21 (file 3, block 61217)
Bad header found during crash/instance recovery
Data in bad block:
 type: 6 format: 1 rdba: 0x000000c0
 last change scn: 0x4f2b.ef213393 seq: 0xd flg: 0xe1
 spare1: 0x20 spare2: 0xa2 spare3: 0x41c5
 consistency value in tail: 0x00004f2b
 check value in block header: 0x104
 block checksum disabled
Reread of rdba: 0x00c0ef21 (file 3, block 61217) found same corrupted data
 from side 
Reread of rdba: 0x00c0ef21 (file 3, block 61217) found same corrupted data
 from side 
………………一直循报file 3 block 61217坏块错误

对于这种情况,尝试人工recover datafile文件

SYS@orcl1>recover datafile 1;
Media recovery complete.
SYS@orcl1>recover datafile 2;
Media recovery complete.
SYS@orcl1>recover datafile 4,5,6,7,8,9;
ORA-00283: recovery session canceled due to errors
ORA-12805: parallel query server died unexpectedly


SYS@orcl1>recover datafile 4;
Media recovery complete.
SYS@orcl1>recover datafile 6,7,8,9;
Media recovery complete.
SYS@orcl1>recover datafile 10,11,12,13,14;
ORA-00279: change 15260723994623 generated at 12/10/2024 06:52:06 needed for thread 2
ORA-00289: suggestion : /oracle/db10g/dbs/arch/2_61129_726871555.dbf
ORA-00280: change 15260723994623 for thread 2 is in sequence #61129


Specify log: {<RET>=suggested | filename | AUTO | CANCEL}
cancel
Media recovery cancelled.
SYS@orcl1>recover datafile 10,11,12,14;
Media recovery complete.
SYS@orcl1>recover datafile 15,16,17,19,20,21,22,23,24,25;
Media recovery complete.
SYS@orcl1>recover datafile 26,27,28,29,30,32,31;
Media recovery complete.

这里有几个文件没有recover 成功,有些是坏块,有些是缺少归档,对于这种情况一般有两种处理思路:
1. 通过屏蔽一致性,强制把库拉起来
2. 通过bbed修改文件头,然后直接正常open库,这里我们选择了第二种方法,把异常的几个数据文件头状态修改和file 1的一样(这里为什么没有使用obet(Oracle Block Editor Tool),不是obet没有这个功能,是由于obet我没有在aix平台进行编译)

BBED> set file 1
        FILE#           1

BBED> p kcvfh.kcvfhckp
struct kcvfhckp, 160 bytes                  @484     
   struct kcvcpscn, 8 bytes                 @484     
      ub4 kscnbas                           @484      0x3393501d
      ub2 kscnwrp                           @488      0x0de1
   ub4 kcvcptim                             @492      0x492a5f83
   ub2 kcvcpthr                             @496      0x0002
   union u, 12 bytes                        @500     
      struct kcvcprba, 12 bytes             @500     
         ub4 kcrbaseq                       @500      0x0000eef2
         ub4 kcrbabno                       @504      0x001a4986
         ub2 kcrbabof                       @508      0x0010


BBED> set file 3
        FILE#           3

BBED> p kcvfh.kcvfhckp
struct kcvfhckp, 160 bytes                  @484     
   struct kcvcpscn, 8 bytes                 @484     
      ub4 kscnbas                           @484      0x338943b6
      ub2 kscnwrp                           @488      0x0de1
   ub4 kcvcptim                             @492      0x491973d8
   ub2 kcvcpthr                             @496      0x0002
   union u, 12 bytes                        @500     
      struct kcvcprba, 12 bytes             @500     
         ub4 kcrbaseq                       @500      0x0000eef2
         ub4 kcrbabno                       @504      0x00000002
         ub2 kcrbabof                       @508      0x0010

然后对这些异常文件进行recover 操作

SYS@orcl1>recover datafile 3;
Media recovery complete.
SYS@orcl1>recover datafile 5;
Media recovery complete.
SYS@orcl1>recover datafile 13,18;
Media recovery complete.


Mon Nov  2 10:32:05 2026
ALTER DATABASE RECOVER  datafile 3  
Mon Nov  2 10:32:05 2026
Media Recovery Start
 parallel recovery started with 15 processes
Mon Nov  2 10:32:07 2026
Recovery of Online Redo Log: Thread 2 Group 4 Seq 61170 Reading mem 0
  Mem# 0: /oracle/oradata/db_ro41_1g
  Mem# 1: /oracle/oradata/db_ro42_1g
Mon Nov  2 10:32:07 2026
Recovery of Online Redo Log: Thread 1 Group 2 Seq 107734 Reading mem 0
  Mem# 0: /oracle/oradata/db_ro21_1g
  Mem# 1: /oracle/oradata/db_ro22_1g
Mon Nov  2 10:32:07 2026
Media Recovery Complete (orcl1)
Completed: ALTER DATABASE RECOVER  datafile 3  
Mon Nov  2 10:32:16 2026
ALTER DATABASE RECOVER  datafile 5  
Media Recovery Start
 parallel recovery started with 15 processes
Mon Nov  2 10:32:16 2026
Recovery of Online Redo Log: Thread 2 Group 4 Seq 61170 Reading mem 0
  Mem# 0: /oracle/oradata/db_ro41_1g
  Mem# 1: /oracle/oradata/db_ro42_1g
Mon Nov  2 10:32:16 2026
Recovery of Online Redo Log: Thread 1 Group 2 Seq 107734 Reading mem 0
  Mem# 0: /oracle/oradata/db_ro21_1g
  Mem# 1: /oracle/oradata/db_ro22_1g
Mon Nov  2 10:32:16 2026
Media Recovery Complete (orcl1)
Completed: ALTER DATABASE RECOVER  datafile 5  
Mon Nov  2 10:32:22 2026
ALTER DATABASE RECOVER  datafile 13,18  
Media Recovery Start
 parallel recovery started with 15 processes
Mon Nov  2 10:32:22 2026
Recovery of Online Redo Log: Thread 2 Group 4 Seq 61170 Reading mem 0
  Mem# 0: /oracle/oradata/db_ro41_1g
  Mem# 1: /oracle/oradata/db_ro42_1g
Mon Nov  2 10:32:22 2026
Recovery of Online Redo Log: Thread 1 Group 2 Seq 107734 Reading mem 0
  Mem# 0: /oracle/oradata/db_ro21_1g
  Mem# 1: /oracle/oradata/db_ro22_1g
Mon Nov  2 10:32:22 2026
Media Recovery Complete (orcl1)
Completed: ALTER DATABASE RECOVER  datafile 13,18 

直接打开数据库

$ sqlplus / as sysdba

SQL*Plus: Release 10.2.0.4.0 - Production on Mon Nov 2 10:33:27 2026

Copyright (c) 1982, 2007, Oracle.  All Rights Reserved.


Connected to:
Oracle Database 10g Enterprise Edition Release 10.2.0.4.0 - 64bit Production
With the Partitioning, Real Application Clusters, OLAP, Data Mining
and Real Application Testing options
            
SYS@orcl1>set pages 10000
SYS@orcl1>set numw 16
SYS@orcl1>SELECT status,
  2  checkpoint_change#,
  3  to_char(checkpoint_time,'yyyy-mm-dd hh24:mi:ss') checkpoint_time,
  4  last_change#,
  5  count(*) ROW_NUM
  6  FROM v$datafile
  7  GROUP BY status, checkpoint_change#, checkpoint_time,last_change#
  8  ORDER BY status, checkpoint_change#, checkpoint_time;

STATUS  CHECKPOINT_CHANGE# CHECKPOINT_TIME         LAST_CHANGE#          ROW_NUM
------- ------------------ ------------------- ---------------- ----------------
ONLINE      15260884095005 2026-03-10 08:02:11   15260884095005               27
ONLINE      15260884095006 2026-03-10 08:02:11   15260884095006                4
SYSTEM      15260884095005 2026-03-10 08:02:11   15260884095005                1

SYS@orcl1>
SYS@orcl1>
SYS@orcl1>set numw 16
SYS@orcl1>col CHECKPOINT_TIME for a40
SYS@orcl1>set lines 150
SYS@orcl1>set pages 1000
SYS@orcl1>SELECT status,
  2  to_char(checkpoint_time,'yyyy-mm-dd hh24:mi:ss') checkpoint_time,FUZZY,checkpoint_change#,
  3  count(*) ROW_NUM
  4  FROM v$datafile_header
  5  GROUP BY status, checkpoint_change#, to_char(checkpoint_time,'yyyy-mm-dd hh24:mi:ss'),fuzzy
  6  ORDER BY status, checkpoint_change#, checkpoint_time;

STATUS  CHECKPOINT_TIME                          FUZ CHECKPOINT_CHANGE#          ROW_NUM
------- ---------------------------------------- --- ------------------ ----------------
ONLINE  2026-03-10 08:02:11                      NO      15260884095005               28
ONLINE  2026-03-10 08:02:11                      NO      15260884095006                4

SYS@orcl1>alter database open;

Database altered.

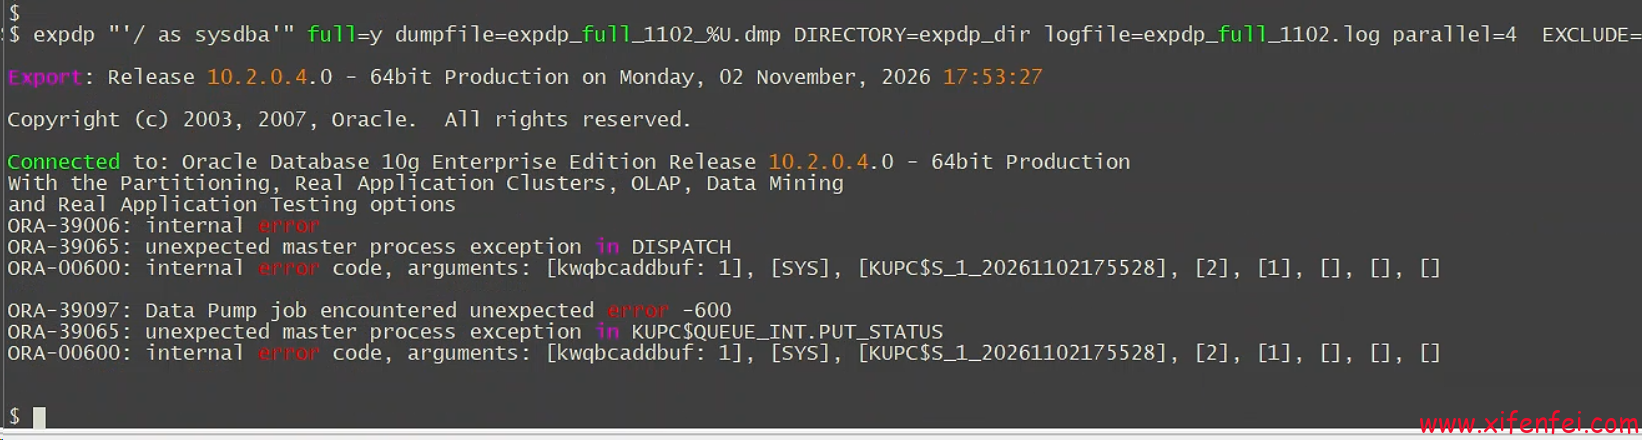
然后尝试expdp导出数据报ORA-600 kwqbcaddbuf: 1错误

$ expdp "'/ as sysdba'" full=y dumpfile=expdp_full_1102_%U.dmp DIRECTORY=expdp_dir logfile=expdp_full_1102.log
> parallel=4  EXCLUDE=STATISTICS,AUDIT

Export: Release 10.2.0.4.0 - 64bit Production on Monday, 02 November, 2026 10:38:48

Copyright (c) 2003, 2007, Oracle.  All rights reserved.

Connected to: Oracle Database 10g Enterprise Edition Release 10.2.0.4.0 - 64bit Production
With the Partitioning, Real Application Clusters, OLAP, Data Mining
and Real Application Testing options
ORA-39006: internal error
ORA-39065: unexpected master process exception in DISPATCH
ORA-00600: internal error code, arguments: [kwqbcaddbuf: 1], [SYS], [KUPC$S_1_20261102104051], [2], [1], [], [], []

ORA-39097: Data Pump job encountered unexpected error -600
ORA-39065: unexpected master process exception in KUPC$QUEUE_INT.PUT_STATUS
ORA-00600: internal error code, arguments: [kwqbcaddbuf: 1], [SYS], [KUPC$S_1_20261102104051], [2], [1], [], [], []

kwqbcaddbuf


通过rebuild datapump程序

@?/rdbms/admin/catdph.sql
@?/rdbms/admin/catmetx.sql
@?/rdbms/admin/prvtdtde.plb
@?/rdbms/admin/catdpb.sql
@?/rdbms/admin/dbmspump.sql
@?/rdbms/admin/utlrp.sql

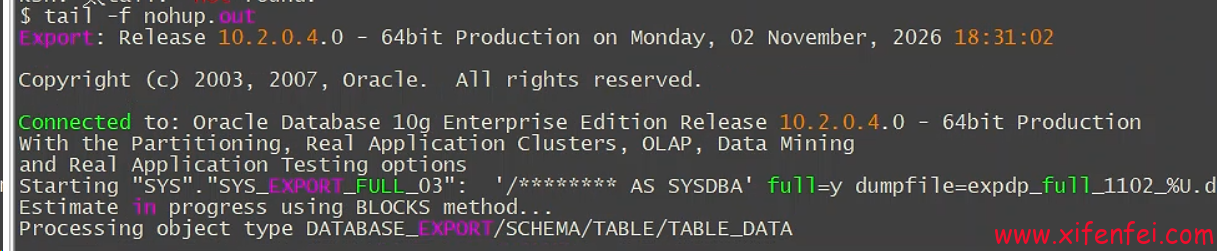
实现expdp程序可以正常导出数据
11


断电引起ORA-600 3005故障处理

联系:手机/微信(+86 17813235971) QQ(107644445)QQ咨询惜分飞

标题:断电引起ORA-600 3005故障处理

作者:惜分飞©版权所有[未经本人同意,不得以任何形式转载,否则有进一步追究法律责任的权利.]

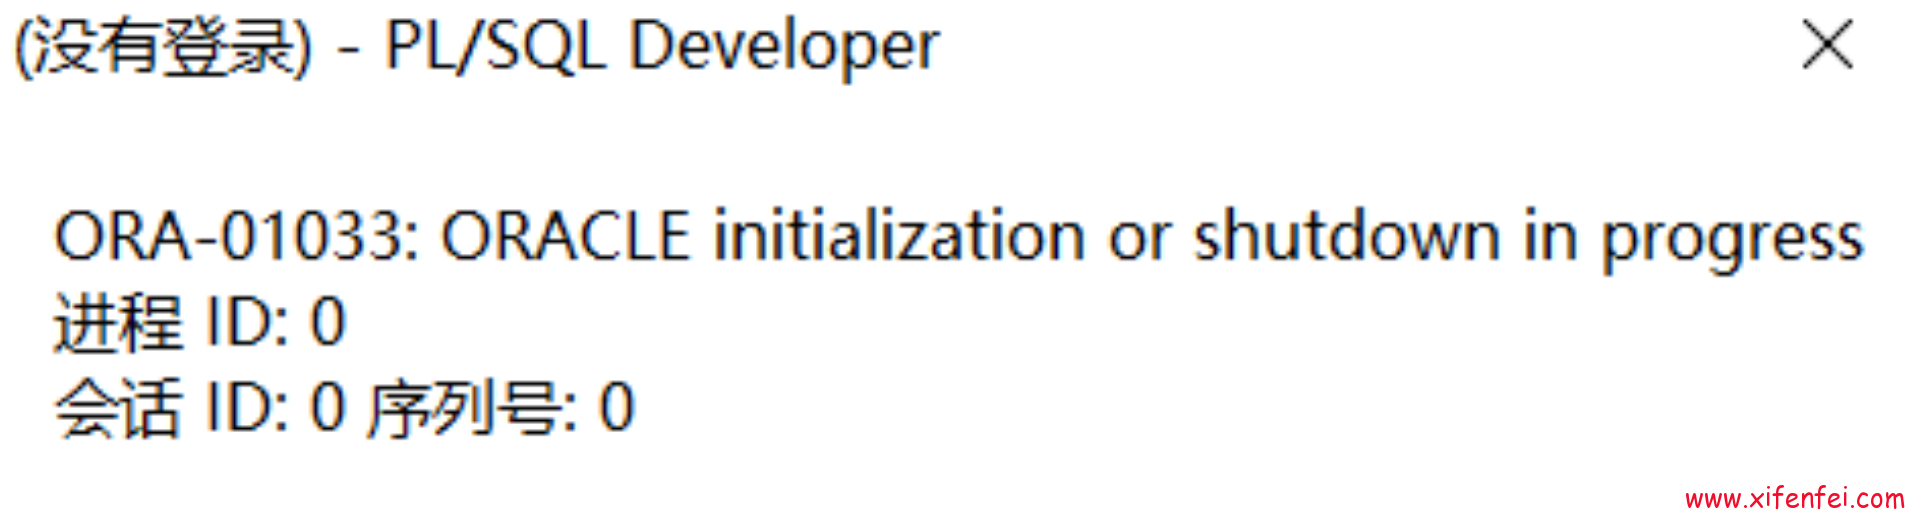
异常断电之后,客户连接数据库报ORA-01033: ORACLE initialization or shutdown in progress错误,该错误一般是由于数据库没有正常open成功导致.
ORA-01033
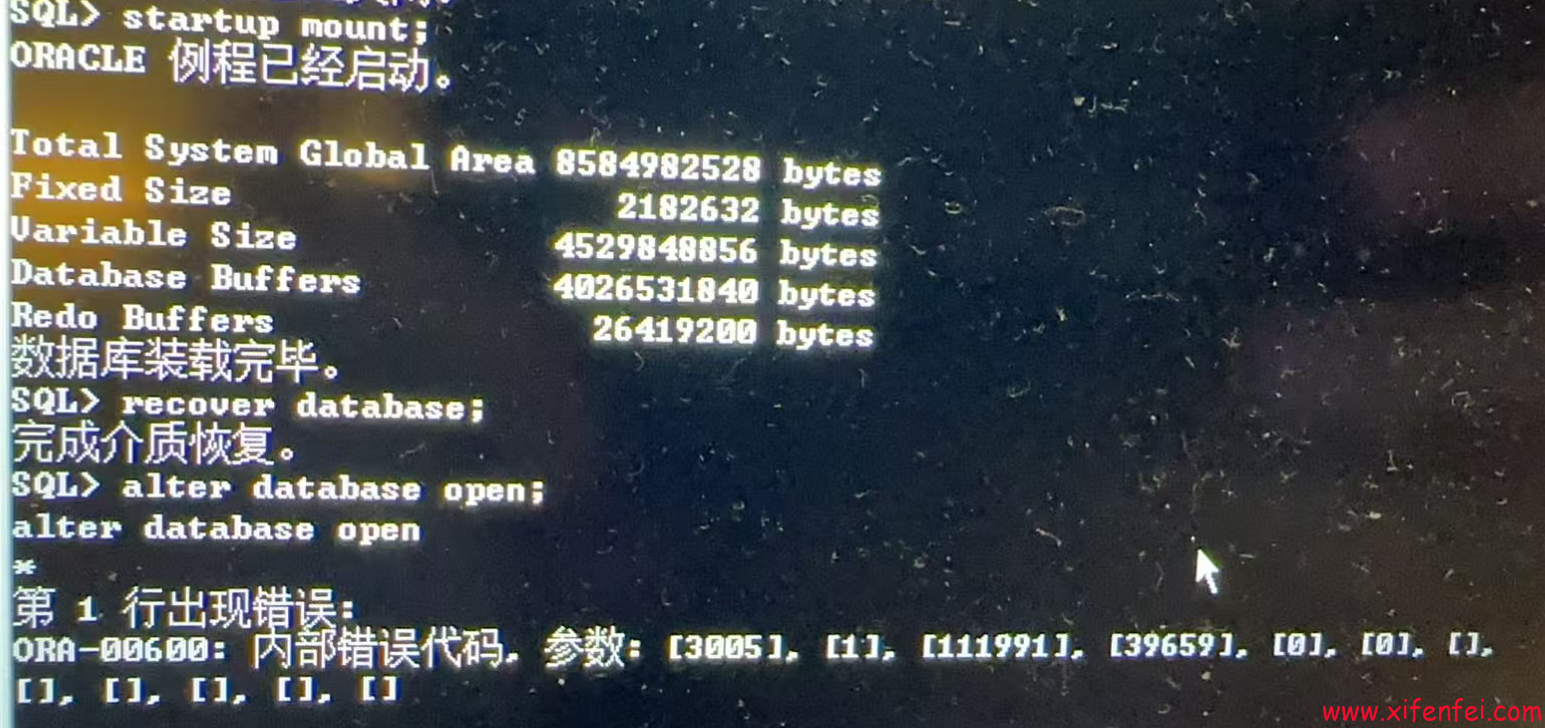
尝试人工启动数据库报ORA-600 3005错误
ORA-600-3005

Tue Oct 27 19:02:59 2026
ALTER DATABASE RECOVER  database  
Media Recovery Start
 started logmerger process
Parallel Media Recovery started with 16 slaves
Tue Oct 27 19:03:00 2026
Recovery of Online Redo Log: Thread 1 Group 3 Seq 111990 Reading mem 0
  Mem# 0: D:\orcl\REDO03.LOG
Completed: ALTER DATABASE RECOVER  database  
Tue Oct 27 19:03:22 2026
alter database open
Beginning crash recovery of 1 threads
 parallel recovery started with 15 processes
Started redo scan
Errors in file d:\app\administrator\diag\rdbms\orcl\orcl\trace\orcl_ora_1908.trc  (incident=917810):
ORA-00600: 内部错误代码, 参数: [3005], [1], [111991], [39659], [0], [0], [], [], [], [], [], []
Incident details in: d:\app\administrator\diag\rdbms\orcl\orcl\incident\incdir_917810\orcl_ora_1908_i917810.trc
Aborting crash recovery due to error 600
Errors in file d:\app\administrator\diag\rdbms\orcl\orcl\trace\orcl_ora_1908.trc:
ORA-00600: 内部错误代码, 参数: [3005], [1], [111991], [39659], [0], [0], [], [], [], [], [], []
Errors in file d:\app\administrator\diag\rdbms\orcl\orcl\trace\orcl_ora_1908.trc:
ORA-00600: 内部错误代码, 参数: [3005], [1], [111991], [39659], [0], [0], [], [], [], [], [], []
ORA-600 signalled during: alter database open...

这个错误是一个较为常见的错误,由于redo日志或者thread信息丢失导致.检查数据文件头状态一致而且干净

SQL> set pages 10000
SQL> set numw 16
SQL> SELECT status,
  2  checkpoint_change#,
  3  to_char(checkpoint_time,'yyyy-mm-dd hh24:mi:ss') checkpoint_time,
  4  last_change#,
  5  count(*) ROW_NUM
  6  FROM v$datafile
  7  GROUP BY status, checkpoint_change#, checkpoint_time,last_change#
  8  ORDER BY status, checkpoint_change#, checkpoint_time;

STATUS  CHECKPOINT_CHANGE# CHECKPOINT_TIME         LAST_CHANGE#          ROW_NUM
------- ------------------ ------------------- ---------------- ----------------
RECOVER        27917313690 2026-10-27 14:51:31                                14
SYSTEM         27917313690 2026-10-27 14:51:31                                 3

SQL>
SQL>
SQL> set numw 16
SQL> col CHECKPOINT_TIME for a40
SQL> set lines 150
SQL> set pages 1000
SQL> SELECT status,
  2  to_char(checkpoint_time,'yyyy-mm-dd hh24:mi:ss') checkpoint_time,FUZZY,checkpoint_change#,
  3  count(*) ROW_NUM
  4  FROM v$datafile_header
  5  GROUP BY status, checkpoint_change#, to_char(checkpoint_time,'yyyy-mm-dd hh24:mi:ss'),fuzzy
  6  ORDER BY status, checkpoint_change#, checkpoint_time;

STATUS  CHECKPOINT_TIME                          FUZ CHECKPOINT_CHANGE#          ROW_NUM
------- ---------------------------------------- --- ------------------ ----------------
ONLINE  2026-10-27 14:51:31                      NO         27917313690               17

基于这种情况,直接可以打开数据库,检测字典一致,基本上可以实现0丢失

SQL> alter database open resetlogs;

数据库已更改。

SQL> @D:/HCHECK
HCheck Version 07MAY18 on 28-10月-2026 12:20:10
----------------------------------------------
Catalog Version 11.2.0.1.0 (1102000100)
db_name: ORCL

                                   Catalog       Fixed
Procedure Name                     Version    Vs Release    Timestamp
Result
------------------------------ ... ---------- -- ---------- --------------
------
.- LobNotInObj                 ... 1102000100 <=  *All Rel* 10/28 12:20:11 PASS
.- MissingOIDOnObjCol          ... 1102000100 <=  *All Rel* 10/28 12:20:11 PASS
.- SourceNotInObj              ... 1102000100 <=  *All Rel* 10/28 12:20:11 PASS
.- IndIndparMismatch           ... 1102000100 <= 1102000100 10/28 12:20:12 PASS
.- InvCorrAudit                ... 1102000100 <= 1102000100 10/28 12:20:12 PASS
.- OversizedFiles              ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- PoorDefaultStorage          ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- PoorStorage                 ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- PartSubPartMismatch         ... 1102000100 <= 1102000100 10/28 12:20:12 PASS
.- TabPartCountMismatch        ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedTabComPart          ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- MissingSum$                 ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- MissingDir$                 ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- DuplicateDataobj            ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- ObjSynMissing               ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- ObjSeqMissing               ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedUndo                ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedIndex               ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedIndexPartition      ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedIndexSubPartition   ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedTable               ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedTablePartition      ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedTableSubPartition   ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- MissingPartCol              ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedSeg$                ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedIndPartObj#         ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- DuplicateBlockUse           ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- FetUet                      ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- Uet0Check                   ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- ExtentlessSeg               ... 1102000100 <= 1102000100 10/28 12:20:12 PASS
.- SeglessUET                  ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- BadInd$                     ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- BadTab$                     ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- BadIcolDepCnt               ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- ObjIndDobj                  ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- TrgAfterUpgrade             ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- ObjType0                    ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- BadOwner                    ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- StmtAuditOnCommit           ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- BadPublicObjects            ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- BadSegFreelist              ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- BadDepends                  ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- CheckDual                   ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- ObjectNames                 ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- BadCboHiLo                  ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- ChkIotTs                    ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- NoSegmentIndex              ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- BadNextObject               ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- DroppedROTS                 ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- FilBlkZero                  ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- DbmsSchemaCopy              ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- OrphanedObjError            ... 1102000100 >  1102000000 10/28 12:20:13 PASS
.- ObjNotLob                   ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- MaxControlfSeq              ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- SegNotInDeferredStg         ... 1102000100 >  1102000000 10/28 12:20:14 PASS
.- SystemNotRfile1             ... 1102000100 >   902000000 10/28 12:20:14 PASS
.- DictOwnNonDefaultSYSTEM     ... 1102000100 <=  *All Rel* 10/28 12:20:14 PASS
.- OrphanTrigger               ... 1102000100 <=  *All Rel* 10/28 12:20:14 PASS
.- ObjNotTrigger               ... 1102000100 <=  *All Rel* 10/28 12:20:14 PASS
---------------------------------------
28-10月-2026 12:20:14  Elapsed: 4 secs
---------------------------------------
Found 0 potential problem(s) and 0 warning(s)

PL/SQL 过程已成功完成。

基于当前情况,客户可以直接使用当前库,实现最小损失,最快速度恢复.

记录一次云存储资源到期之后引起的数据库恢复

联系:手机/微信(+86 17813235971) QQ(107644445)QQ咨询惜分飞

标题:记录一次云存储资源到期之后引起的数据库恢复

作者:惜分飞©版权所有[未经本人同意,不得以任何形式转载,否则有进一步追究法律责任的权利.]

客户环境是运行在xx厂商上的云环境的Oracle RAC,由于其中一块asm disk资源到期没有进行续费,云厂商对该盘进行了限速(1MB/s,并且异步写入),导致运行在该rac上的数据库直接crash,客户续费之后磁盘速度恢复正常但是数据库启动报ORA-00353 ORA-00312错误(redo异常),客户找了以前的服务商进行恢复尝试没有成功.对接手后的现场进行检测,发现有20个数据文件被初始化(dbv检测全部是空块,没有写入任何表和索引数据)[直接变成了空文件,一般sqlplus中执行alter database create datafile或者在没有对应的数据文件备份的情况下执行restore datafile会出现这个情况],数据库被强制拉库,但是启动没有成功报ORA-00704 ORA-01555错误.由于客户明天领导会过来检查,所以着急启动系统,我们只能基于现在的现况给客户强制拉起来库,赌运气看看核心业务是否可以跑起来

回溯处理过程,续费欠费资源之后,数据库启动报错(估计是当时限速之后,云存储层面异步写入导致部分写丢失)

Mon Oct 26 11:38:19 2026
alter database open
This instance was first to open
Beginning crash recovery of 1 threads
 parallel recovery started with 15 processes
Started redo scan
Incomplete read from log member '+DATA/xff/onlinelog/group_3.312.1210628353'. Trying next member.
Errors in file /oracle/diag/rdbms/xff/xff1/trace/xff1_ora_19144.trc  (incident=682004):
ORA-00353: log corruption near block 47146 change 16921129940671 time 10/26/2026 08:57:37
ORA-00312: online log 3 thread 1: '+DATA/xff/onlinelog/group_3.312.1210628353'
Incident details in: /oracle/diag/rdbms/xff/xff1/incident/incdir_682004/xff1_ora_19144_i682004.trc
Abort recovery for domain 0
Aborting crash recovery due to error 368
Errors in file /oracle/diag/rdbms/xff/xff1/trace/xff1_ora_19144.trc:
ORA-00368: checksum error in redo log block
ORA-00353: log corruption near block 47146 change 16921129940671 time 10/26/2026 08:57:37
ORA-00312: online log 3 thread 1: '+DATA/xff/onlinelog/group_3.312.1210628353'
Abort recovery for domain 0
Mon Oct 26 11:38:22 2026
Sweep [inc][682004]: completed
Errors in file /oracle/diag/rdbms/xff/xff1/trace/xff1_ora_19144.trc:
ORA-00368: checksum error in redo log block
ORA-00353: log corruption near block 47146 change 16921129940671 time 10/26/2026 08:57:37
ORA-00312: online log 3 thread 1: '+DATA/xff/onlinelog/group_3.312.1210628353'
ORA-368 signalled during: alter database open...

屏蔽一致性,强制resetlogs的时候报ORA-00704 ORA-01555错误

Mon Oct 26 15:47:43 2026
Setting recovery target incarnation to 2
Initializing SCN for created control file
Database SCN compatibility initialized to 3
Warning - High Database SCN: Current SCN value is 16917769616373, threshold SCN value is 0
Mon Oct 26 15:47:43 2026
Assigning activation ID 2556751686 (0x9864ef46)
LGWR: STARTING ARCH PROCESSES
Mon Oct 26 15:47:43 2026
ARC0 started with pid=32, OS id=14392 
ARC0: Archival started
LGWR: STARTING ARCH PROCESSES COMPLETE
ARC0: STARTING ARCH PROCESSES
Mon Oct 26 15:47:44 2026
ARC1 started with pid=33, OS id=14446 
Mon Oct 26 15:47:44 2026
ARC2 started with pid=34, OS id=14448 
Mon Oct 26 15:47:44 2026
ARC3 started with pid=35, OS id=14450 
ARC1: Archival started
ARC2: Archival started
ARC1: Becoming the 'no FAL' ARCH
ARC1: Becoming the 'no SRL' ARCH
ARC2: Becoming the heartbeat ARCH
Thread 1 opened at log sequence 1
  Current log# 1 seq# 1 mem# 0: +DATA/xff/onlinelog/group_1.314.1210628351
Successful open of redo thread 1
MTTR advisory is disabled because FAST_START_MTTR_TARGET is not set
Mon Oct 26 15:47:44 2026
SMON: enabling cache recovery
ORA-01555 caused by SQL statement below (SQL ID: 7bd391hat42zk, SCN: 0x0f62.f9a5fbf8):
select /*+ rule */ name,file#,block#,status$,user#,undosqn,xactsqn,scnbas,scnwrp,
DECODE(inst#,0,NULL,inst#),ts#,spare1 from undo$ where us#=:1
Errors in file /oracle/diag/rdbms/xff/xff1/trace/xff1_ora_13439.trc:
ORA-00704: bootstrap process failure
ORA-00604: error occurred at recursive SQL level 2
ORA-01555: snapshot too old: rollback segment number 0 with name "SYSTEM" too small
Errors in file /oracle/diag/rdbms/xff/xff1/trace/xff1_ora_13439.trc:
ORA-00704: bootstrap process failure
ORA-00604: error occurred at recursive SQL level 2
ORA-01555: snapshot too old: rollback segment number 0 with name "SYSTEM" too small
Error 704 happened during db open, shutting down database
USER (ospid: 13439): terminating the instance due to error 704
Instance terminated by USER, pid = 13439
ORA-1092 signalled during: ALTER DATABASE OPEN RESETLOGS...
opiodr aborting process unknown ospid (13439) as a result of ORA-1092

从这个时候开始我接手这个故障,数据完全恢复已经不太可能,只能基于现在的情况,给客户尝试拉起来库,看看核心业务是否可以跑起来.
数据库open过程报ORA-01555错误,这个是一个比较常见的问题,以前专门写过类似文章:
在数据库open过程中常遇到ORA-01555汇总
数据库open过程遭遇ORA-1555对应sql语句补充
对于这个客户问题,我也一样尝试修改scn的方式来解决

SQL> set numw 16
col CHECKPOINT_TIME for a40
set lines 150
set pages 1000
SELECT status,
to_char(checkpoint_time,'yyyy-mm-dd hh24:mi:ss') checkpoint_time,FUZZY,checkpoint_change#,
count(*) ROW_NUM
FROM v$datafile_header
GROUP BY status, checkpoint_change#, to_char(checkpoint_time,'yyyy-mm-dd hh24:mi:ss'),fuzzy
ORDER BY status, checkpoint_change#, checkpoint_time;SQL> SQL> SQL> SQL>   2    3    4    5    6  

STATUS  CHECKPOINT_TIME                          FUZ CHECKPOINT_CHANGE#          ROW_NUM
------- ---------------------------------------- --- ------------------ ----------------
ONLINE  2026-10-26 15:47:44                      YES     16917769616374              191

使用obet的patch_scn功能来修改数据库scn(obet的patch_scn功能)

OBET> patch_scn 89103 0x06001AE70 0xF62FBA5FBF6
 
=== Oracle SCN Patch ===
PID:     89103
Address: 0x06001AE70
New Value: 0xF62FBA5FBF6 (16917803170806)
Original SCN: 0x0
 
Are you sure you want to modify Oracle SCN? (yes/no): y
 
SCN modified: 0x0 -> 0xF62FBA5FBF6
Oracle SCN successfully modified.


SQL> oradebug DUMPvar SGA kcsgscn_ 
kcslf kcsgscn_ [06001AE70, 06001AEA0) = FBA5FBF6 00000F62 00000000 00000000 00000000

然后尝试打开数据库依旧报ORA-01555错误,证明我们处理的scn不正确

SQL> recover database using backup controlfile;
ORA-00279: change 16917769616374 generated at 10/26/2026 15:47:44 needed for
thread 1
ORA-00289: suggestion : +ARCH
ORA-00280: change 16917769616374 for thread 1 is in sequence #1


Specify log: {<RET>=suggested | filename | AUTO | CANCEL}
+DATA/xff/onlinelog/group_1.314.1210628351
Log applied.
Media recovery complete.
SQL> alter database open resetlogs;
alter database open resetlogs
*
ERROR at line 1:
ORA-01092: ORACLE instance terminated. Disconnection forced
ORA-00704: bootstrap process failure
ORA-00604: error occurred at recursive SQL level 2
ORA-01555: snapshot too old: rollback segment number 0 with name "SYSTEM" too small
Process ID: 18169
Session ID: 3681 Serial number: 2825

分析异常block的scn

*** 2026-10-27 01:05:42.156
Start dump data block from file +DATA/xff/system01.dbf minblk 558 maxblk 558
 V10 STYLE FILE HEADER:
        Compatibility Vsn = 186647552=0xb200400
        Db ID=2195614447=0x82de6aef, Db Name='xff'
        Activation ID=0=0x0
        Control Seq=542=0x21e, File size=446720=0x6d100
        File Number=1, Blksiz=8192, File Type=3 DATA
Dump all the blocks in range:
buffer tsn: 0 rdba: 0x0040022e (1/558)
scn: 0x0f63.c1efd2ab seq: 0x01 flg: 0x04 tail: 0xd2ab0201
frmt: 0x02 chkval: 0x75a3 type: 0x02=KTU UNDO BLOCK
Hex dump of block: st=0, typ_found=1

发现该block的scn非常大0x0f63.c1efd2ab,我之前处理的scn明显不合适,继续换上新的scn,再次打开数据库成功

OBET> patch_scn 89103 0x06001AE70 0xF64C1EFD2AB
 
=== Oracle SCN Patch ===
PID:     89103
Address: 0x06001AE70
New Value: 0xF64C1EFD2AB(16925424865963)
Original SCN: 0x0
 
Are you sure you want to modify Oracle SCN? (yes/no): y
 
SCN modified: 0x0 -> 0xF64C1EFD2AB
Oracle SCN successfully modified.


SQL> oradebug DUMPvar SGA kcsgscn_ 
kcslf kcsgscn_ [06001AE70, 06001AEA0) = C1EFD2AB 00000F64 00000000 00000000 00000000
SQL> 

SQL> 
SQL> 
SQL> alter database open;

Database altered.
[/sql]
后续大量异常undo问题
1
ORA-00376: file 182 cannot be read at this time
ORA-01111: name for data file 182 is unknown - rename to correct file
ORA-01110: data file 182: '/oracle/product/11.2.0/db_1/dbs/MISSING00182'
ORACLE Instance xff1 (pid = 20) - Error 1578 encountered while recovering transaction (21, 29) on object 99404.
Errors in file /oracle/diag/rdbms/xff/xff1/trace/xff1_smon_29435.trc:
ORA-01578: ORACLE data block corrupted (file # 8, block # 1471227)
ORA-01110: data file 8: '+DATA/xff/users04.dbf'
ORACLE Instance xff1 (pid = 20) - Error 376 encountered while recovering transaction (2, 27) on object 599926.
Errors in file /oracle/diag/rdbms/xff/xff1/trace/xff1_smon_29435.trc:
ORA-00376: file 211 cannot be read at this time
ORA-01111: name for data file 211 is unknown - rename to correct file
ORA-01110: data file 211: '/oracle/product/11.2.0/db_1/dbs/MISSING00211'
ORACLE Instance xff1 (pid = 20) - Error 376 encountered while recovering transaction (10, 6) on object 99591.
Errors in file /oracle/diag/rdbms/xff/xff1/trace/xff1_smon_29435.trc:
ORA-00376: file 182 cannot be read at this time
ORA-01111: name for data file 182 is unknown - rename to correct file
ORA-01110: data file 182: '/oracle/product/11.2.0/db_1/dbs/MISSING0018

由于这些文件已经被初始化掉了,恢复已经没有意义,直接没有加入到ctl中,现在主要是由于有些事务涉及这些文件,导致smon回滚的时候报这些错误,对于这样的异常,直接对于undo进行重建更换新undo即可.处理好这些问题之后,数据库open运行问题,客户自行安排业务测试和论证

Oracle 19c 202610补丁(RUs+OJVM)-19.33

联系:手机/微信(+86 17813235971) QQ(107644445)QQ咨询惜分飞

标题:Oracle 19c 202610补丁(RUs+OJVM)-19.33

作者:惜分飞©版权所有[未经本人同意,不得以任何形式转载,否则有进一步追究法律责任的权利.]

Release Database Update GI Update Windows Bundle Patch
OCT2026 (19.33.0.0.0) 39915792   39922757 39898799
JUL2026 (19.32.0.0.0) 39472050 39467003 39418910
APR2026 (19.31.0.0.0) 39034528 39036936 38818049
JAN2026 (19.30.0.0.0) 38632161 38629535 38597735
OCT2025 (19.29.0.0.0) 38291812 38298204 38111211
JUL2025 (19.28.0.0.0) 37960098 37957391 37962957
APR2025 (19.27.0.0.0) 37642901 37641958 37532350
JAN2025 (19.26.0.0.0) 37260974 37257886 37486199
OCT2024 (19.25.0.0.0) 36912597 36916690 36878821
JUL2024 (19.24.0.0.0) 36582781 36582629 36521936
APR2024 (19.23.0.0.0) 36233263 36233126 36219938
JAN2024 (19.22.0.0.0) 35943157 35940989 35962832
OCT2023 (19.21.0.0.0) 35643107 35642822 35681552
JUL2023 (19.20.0.0.0) 35320081 35319490 35348034
APR2023 (19.19.0.0.0) 35042068 35037840 35046439
JAN2023 (19.18.0.0.0) 34765931 34762026 34750795
Oct2022 (19.17.0.0.0) 34419443 34416665 34468114
JUL2022 (19.16.0.0.0) 34133642 34130714 34110685
APR2022 (19.15.0.0.0) 33806152 33803476 33829175
JAN2022 (19.14.0.0.0) 33515361 33509923 33575656
OCT2021(19.13.0.0.0) 33192793 33182768 33155330
JUL2021 (19.12.0.0.0) 32904851 32895426 32832237
APR2021 (19.11.0.0.0) 32545013 32545008 32409154
JAN2021 (19.10.0.0.0) 32218454 32226239 32062765
OCT2020 (19.9.0.0.0) 31771877 31750108 31719903
JUL2020 (19.8.0.0.0) 31281355 31305339 31247621
APR2020 (19.7.0.0.0) 30869156 30899722 30901317
JAN2020 (19.6.0.0.0) 30557433 30501910 30445947
OCT2019 (19.5.0.0.0) 30125133 30116789 30151705
JUL2019 (19.4.0.0.0) 29834717 29708769 -
APR2019 (19.3.0.0.0) 29517242 29517302 -
Release OJVM Update OJVM + DB Update OJVM + GI Update
OCT2026 (19.33.0.0.261020) 39803650 40121635 40121665
JUL2026 (19.32.0.0.260721) 39222882 39618649 39618711
APR2026 (19.31.0.0.260421) 38906621 39062931 39062956
JAN2026 (19.30.0.0.260120) 38523609 38658587 38658588
OCT2025 (19.29.0.0.251021) 38194382 38273545 38273558
JUL2025 (19.28.0.0.250715) 37847857 37952354 37952382
APR2025 (19.27.0.0.250415) 37499406 37591483 37591516
JAN2025 (19.26.0.0.250121) 37102264 37262172 37262208
OCT2024 (19.25.0.0.241015) 36878697 36866623 36866740
JUL2024 (19.24.0.0.240716) 36414915 36522340 36522439
APR2024 (19.23.0.0.240416) 36199232 36209492 36209493
JAN2024 (19.22.0.0.240116) 35926646 36031426 36031453
OCT2023 (19.21.0.0.231017) 35648110 35742413 35742441
JUL2023 (19.20.0.0.230718) 35354406 35370174 35370167
APR2023 (19.19.0.0.230418) 35050341 35058163 35058172
JAN2023 (19.18.0.0.230117) 34786990 34773489 34773504
OCT2022 (19.17.0.0.221018) 34411846 34449114 34449117
JUL2022 (19.16.0.0.220719) 34086870 34160831 34160854
APR2022 (19.15.0.0.220419) 33808367 33859194 33859214
JAN2022 (19.14.0.0.220118) 33561310 33567270 33567274
OCT2021 (19.13.0.0.211019) 33192694 33248420 33248471
JUL2021 (19.12.0.0.210720) 32876380 32900021 32900083
APR2021 (19.11.0.0.210420) 32399816 32578972 32578973
JAN2021 (19.10.0.0.210119) 32067171 32126828 32126842
OCT2020 (19.9.0.0.201020) 31668882 31720396 31720429
JUL2020 (19.8.0.0.200714) 31219897 31326362 31326369
APR2020 (19.7.0.0.200414) 30805684 30783543 30783556
JAN2020 (19.6.0.0.200114) 30484981 30463595 30463609
OCT2019 (19.5.0.0.191015) 30128191 30133124 30133178
JUL2019 (19.4.0.0.190716) 29774421 29699079 29699097
APR2019 (19.3.0.0.190416) 29548437 29621253 29621299

参考:Assistant: Download Reference for Oracle Database/GI Update, Revision, PSU, SPU(CPU), Bundle Patches, Patchsets and Base Releases KA958